AI Agents Explained Without the Hype
What AI agents are, how they plan and use tools, what they can reliably do today, where they fail, and how to use them safely with the right guardrails.
Retrieval-augmented generation (RAG) explained: how AI answers from your documents, embeddings and vector search, chunking, and why RAG reduces errors.
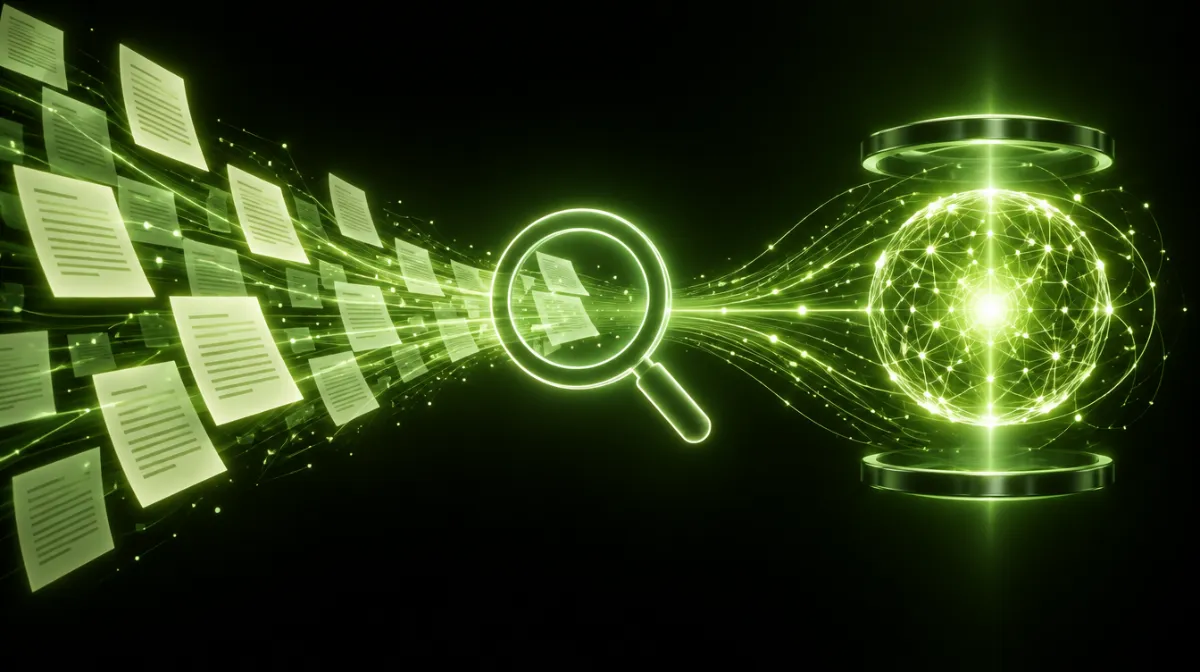
Large language models know a lot, but they don’t know your company’s policies, your product manuals or last week’s meeting notes. Retrieval-augmented generation (RAG) is the technique that lets an AI answer questions from your own documents.
When you ask a question, the system first retrieves the most relevant passages from your documents, then generates an answer using those passages as context.
| Factor | Why it matters |
|---|---|
| Chunking | Chunks too small lose context; too large dilute relevance |
| Search quality | Combining keyword and semantic search often improves results |
| Metadata | Dates, authors and document types help filter results |
| Prompting | Instruct the model to answer only from the context and say when it doesn’t know |
| Evaluation | Test with real questions and check answers against sources |
Fine-tuning changes a model’s behaviour or style by training it on examples. RAG gives it knowledge at question time. For company knowledge that changes often, RAG is usually the better fit; the two can be combined. AI agents often use RAG as one of their tools, too.
Many tools now offer “chat with your documents” features, including the custom assistants built into popular chatbots. Developers can build RAG systems with local models too; see running AI models locally. Engineers will recognise familiar backend concerns, such as caching repeated queries, covered in Backend Architect’s guide to cache-aside, write-through and other caching patterns.
It reduces it significantly, especially with good retrieval and instructions to cite sources, but it doesn’t eliminate it. Keep checking important answers.
Not always. Small projects can use simpler search; vector databases help at larger scale.
Similar in spirit. Chatbots that answer from uploaded files often use retrieval techniques behind the scenes.
Every article is edited by a human and checked against our editorial policy. Spotted a mistake? Tell us.
What AI agents are, how they plan and use tools, what they can reliably do today, where they fail, and how to use them safely with the right guardrails.
How large language models work, in plain English: tokens, training, transformers and attention, fine-tuning, context windows and why they make mistakes.
Why AI chatbots hallucinate, making up facts, quotes and sources with confidence, which tasks are riskiest, and how to reduce errors and check answers.